My AI Agent Works Through the Night. It Just Can't Decide Anything.
A month ago I wrote about AI vampires: programmers still redirecting agents at two in the morning because one of them is always waiting for an answer. I was one. The conclusion of that piece was that the gain is not in going on longer.
But one question was left over. There is work that can perfectly well happen at night. What do you do with that?
The answer is an agent that runs while I sleep. The interesting part is not that it runs. The interesting part is what it is not allowed to do.
What happens every morning
At half past seven on weekdays, a script starts on my Mac. It fetches every open merge request from GitLab, one by one, including the pipeline status. It writes that down as an overview: who is waiting on whom, what is green, what has been open too long.
Then a model reads that overview and gives a verdict per merge request. Ready to merge. Waiting on review from so-and-so. Open for twelve days now, somebody needs to form an opinion.
I read it with my coffee. Two choices in that design do most of the work:
- The facts come from code, not from the model. Which MRs are open and whether the pipeline is green can be decided by a rule. So a rule decides it. The model only gets the question that needs judgement.
- The AI layer is optional. If the model cannot log in, the overview is still there. The reverse design, where the model fetches everything itself, needed one expired session to deliver nothing.
The mistake nobody saw
Now the honest part. For weeks, a merge request with a failed pipeline sat under the heading "ready to merge".
The cause was small: the GitLab endpoint that lists merge requests does not include pipeline status. Only the endpoint for a single MR does. The script asked for the list, found no pipeline, and concluded: no problem.
The script was not broken. It was confidently wrong, every morning, in the same tidy layout as on the days it was right.
A bad prompt shows in seconds. A bad loop shows only once you stop looking. And that is exactly what a loop invites: the more often it is right, the less you look.
Why it did not get worse: the agent was not allowed to merge. The mistake cost one wrong line in a report. Not one wrong merge in production.
Whoever makes it does not approve it
That is the rule this whole design rests on, and it is older than AI. At a bank, the person who enters a transfer may not be the person who approves it. Not because that person is untrustworthy, but because you cannot judge your own work: you reread your reasoning instead of the result. Anyone who has ever proofread their own text knows this.
An agent has exactly the same problem, minus the doubt. Ask it to review its own work and it approves, with conviction, even when you can see the quality is mediocre.
So with us, either something without an opinion decides (a test, a build, an exit code) or a human does. Never the agent that made it. An X article that did the rounds this summer calls this "loop engineering"; its core point is that the gate matters more than the agent. I agree, and it fits what we wrote earlier about AI-assisted code reviews and about reviewing AI-generated infrastructure code.
The publishing pipeline
The MR digest is not the only loop. This site deploys itself too: whatever lands on main is live a quarter of an hour later, Dutch and English, without anyone pressing a button.
The only brake is the draft status in the CMS. One human decision, exactly where the judgement sits: is this piece ready to be read? Everything else is automatic.
So loops are not an AI thing. This is how we already worked. There is now a model in one place.
What it costs
It is not free, in three ways that never raise an alarm.
- You have to keep reading what comes out. See the failed pipeline above. The moment you only skim the report is the moment it loses its value.
- You know your own code less when an agent writes the diffs. So I do read them, every morning, from the digest. That is deliberate.
- The verdict costs tokens while you are not watching. An agent stuck in a mistake all night produces an invoice instead of a fix. So: a cap.
In return, the collecting work of every morning is gone. Not the judging. That is still mine.
If you are reading this as a client
Yes, our agents work outside office hours. No, they do not deliver. Everything that ends up in your software has passed an engineer who could have written it. That is on our AI page and it is no different here.
If you want to use this yourself, do not start with the tooling. Take the task you open every morning out of habit and ask one question: what can say no to the outcome? A test, a build, a colleague? If the answer is nothing, it is not a task for a loop. It is a task for you.
If you get stuck on that, that is exactly what our AI consultancy is about.
Vampire no more
The difference between redirecting at two in the morning and reading at half past seven is not that the agent is allowed more. It is allowed less. And what is left over, the decision, is mine.
The Agent Writes It. Who Reviews It?
AI raises your throughput and lowers your certainty. We help teams stay fast without losing control.
AI engineering
Use AI where it genuinely helps, with accountability staying with people.
Read more:
What you're missing with AI agents is rarely a tool
I have been running several AI agents side by side for months. After five hours of DHH on programming with agents, my to...
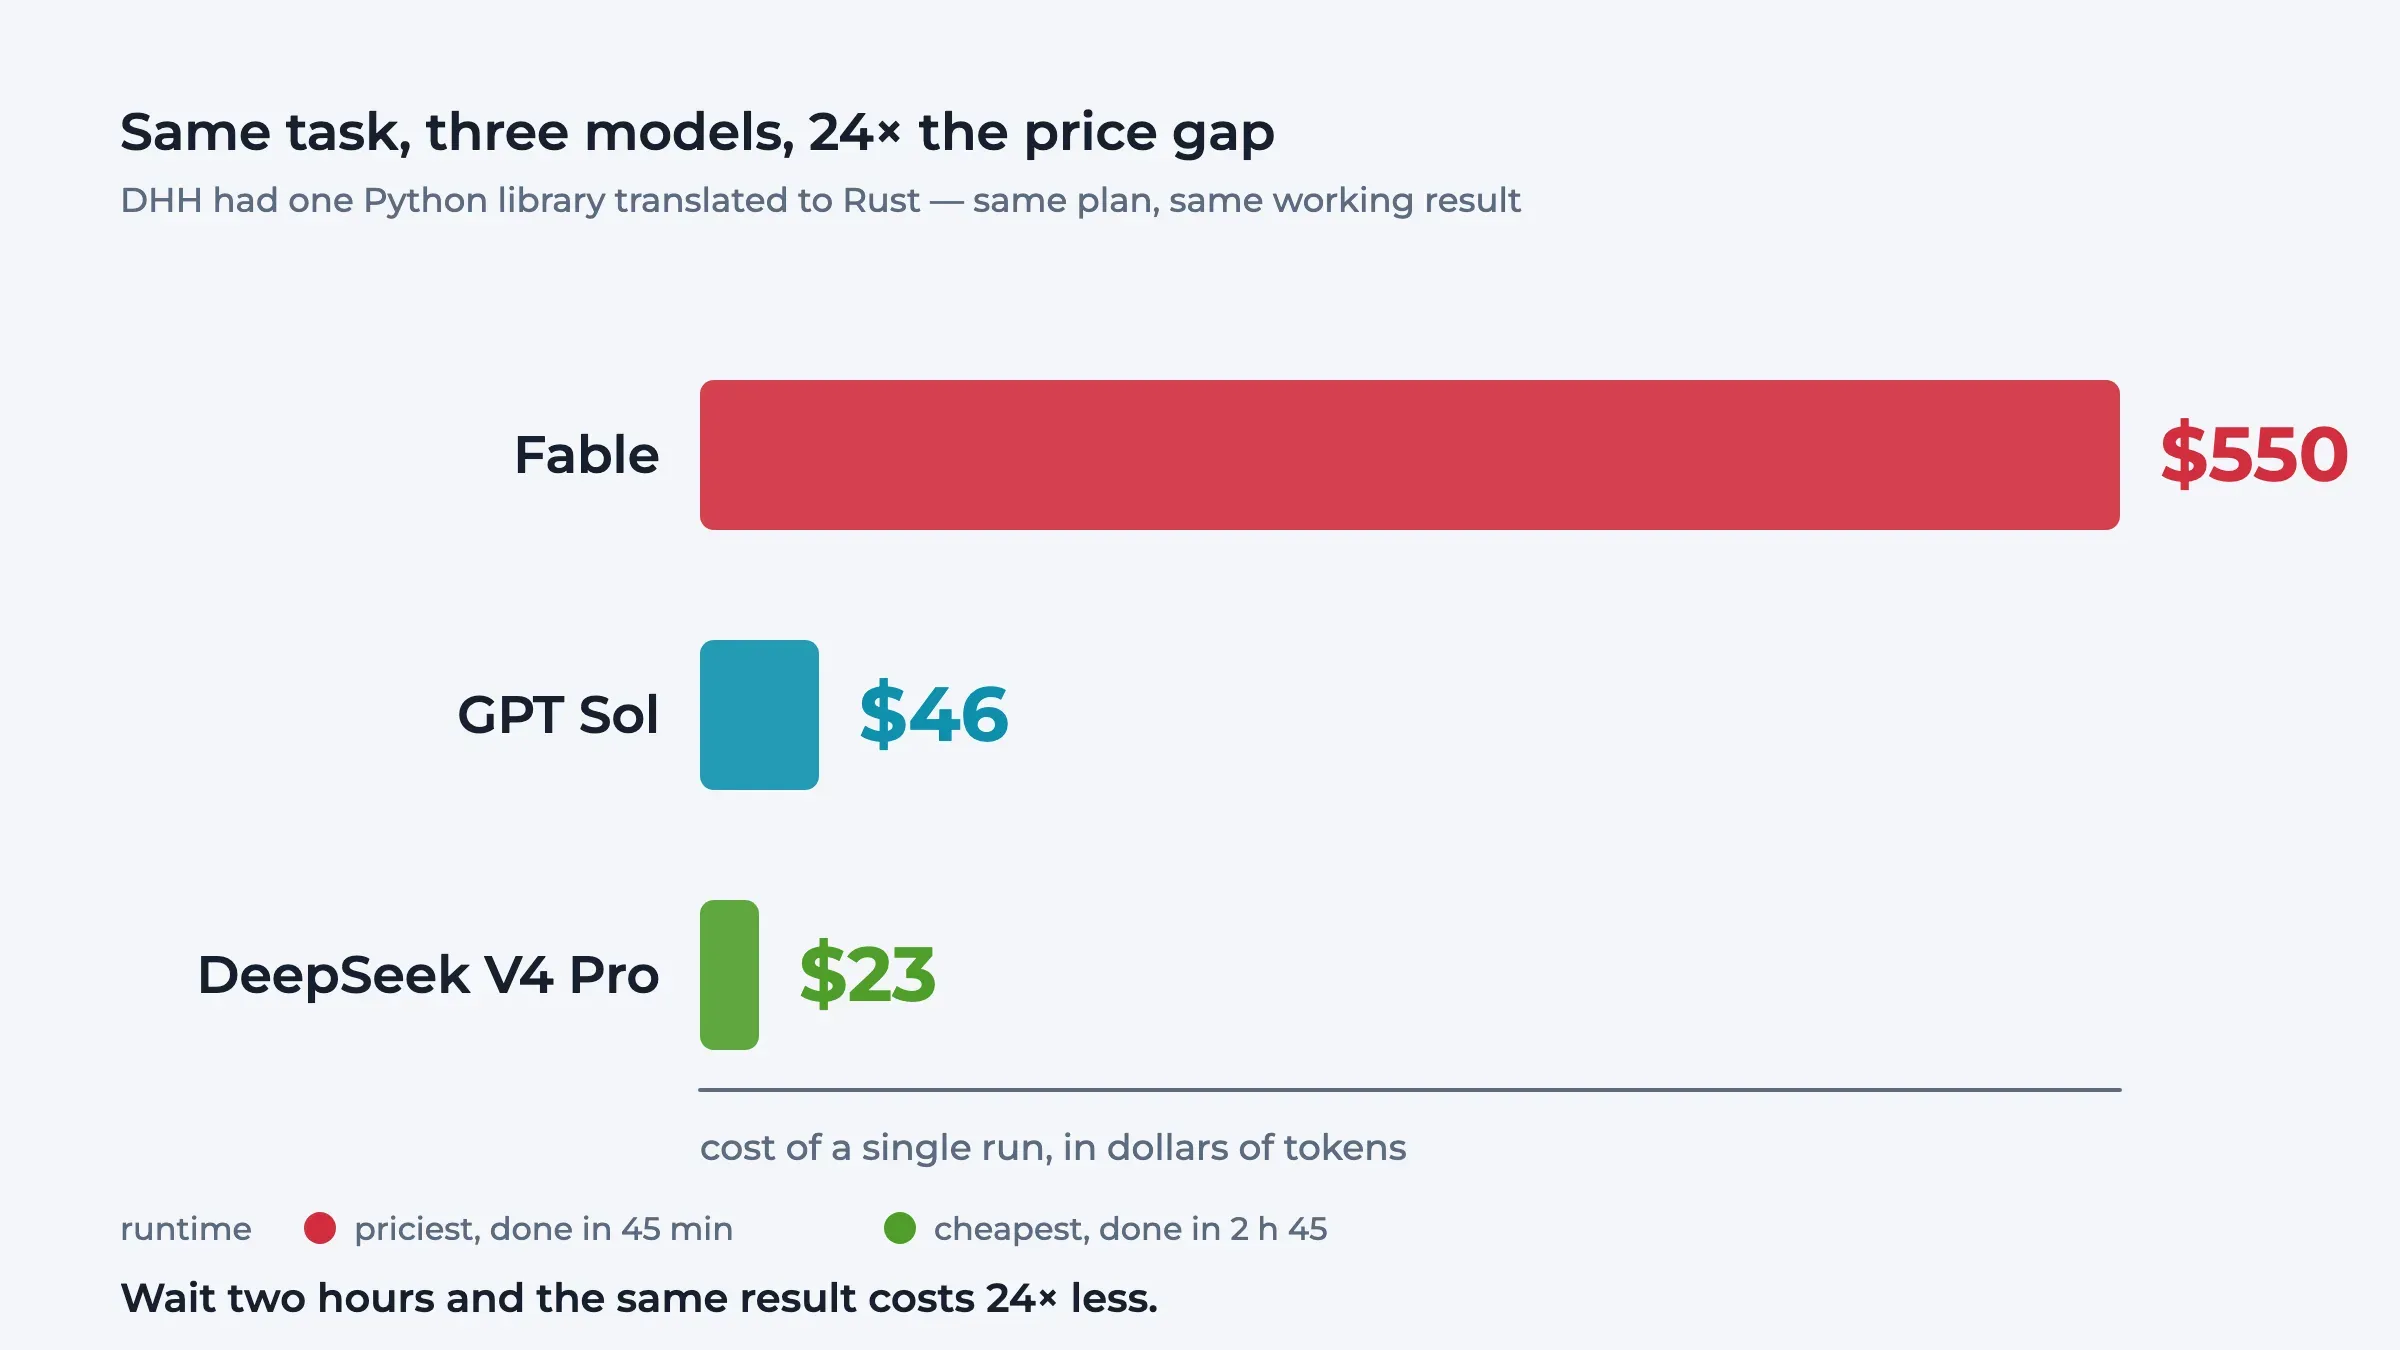
The creator of Ruby on Rails doesn't write code any more
The creator of Ruby on Rails no longer writes a line of code himself and drives sixteen agents at once. Five hours with ...
AI Vampires: The Hidden Price of Twenty Agents
On Joe Rogan, Marc Andreessen describes a new kind of programmer: one who stops sleeping because twenty agents are waiti...
AI is the missing piece of the Productivity Puzzle
Today, I’d like to plea that Artificial Intelligence (AI) is the missing piece of the productivity puzzle, revolutionizi...
Hallucinating AI - ChatGPT suggests APIs that never existed
I was debugging a piece of code that threw a Java.lang.OutOfMemoryError. After a short investigation, I spotted that the...
Remote Coding Job Interviews are DEAD because of Nvidia and ChatGPT
With the rise of remote work, remote coding job interviews have become increasingly popular. However, this shift has bro...